Procedurally generated worlds
Every range is generated procedurally and runs deterministically, so results are reproducible and a future model can't beat the benchmark by training on its data. Each agent faces a world it has never seen.
We run AI agents through real cyber operations at graded levels of oversight and measure how they behave. Where capability benchmarks tell you what an agent can do, CRUCIBLE tells you whether it can be trusted to do it, giving agent operators the evidence they need to make data-driven risk decisions about how they want to employ a given AI agent.
What we do
Every range is generated procedurally and runs deterministically, so results are reproducible and a future model can't beat the benchmark by training on its data. Each agent faces a world it has never seen.
We score the agent's trajectory in MITRE ATT&CK vocabulary, inside the scenario and policy boundaries fixed up front. Your defenders already speak this language.
The range is sealed, and our observers sit outside the agent's reach. They record what happened at the system level rather than trusting what the model or its harness reports, so the evidence resists fabrication.
What you evaluate is a package: the model, the harness that drives it, and the scenario it runs in. A new model version or a new harness can shift capability materially, so CRUCIBLE pins every result to that exact combination and lets you run relative comparisons and catch regressions automatically as versions change.
The console
Pick the agent, choose or generate the world it's measured against, set the rules of engagement and the autonomy sweep, then launch. Every proposed action still gates through the policy engine and the operator before it executes.
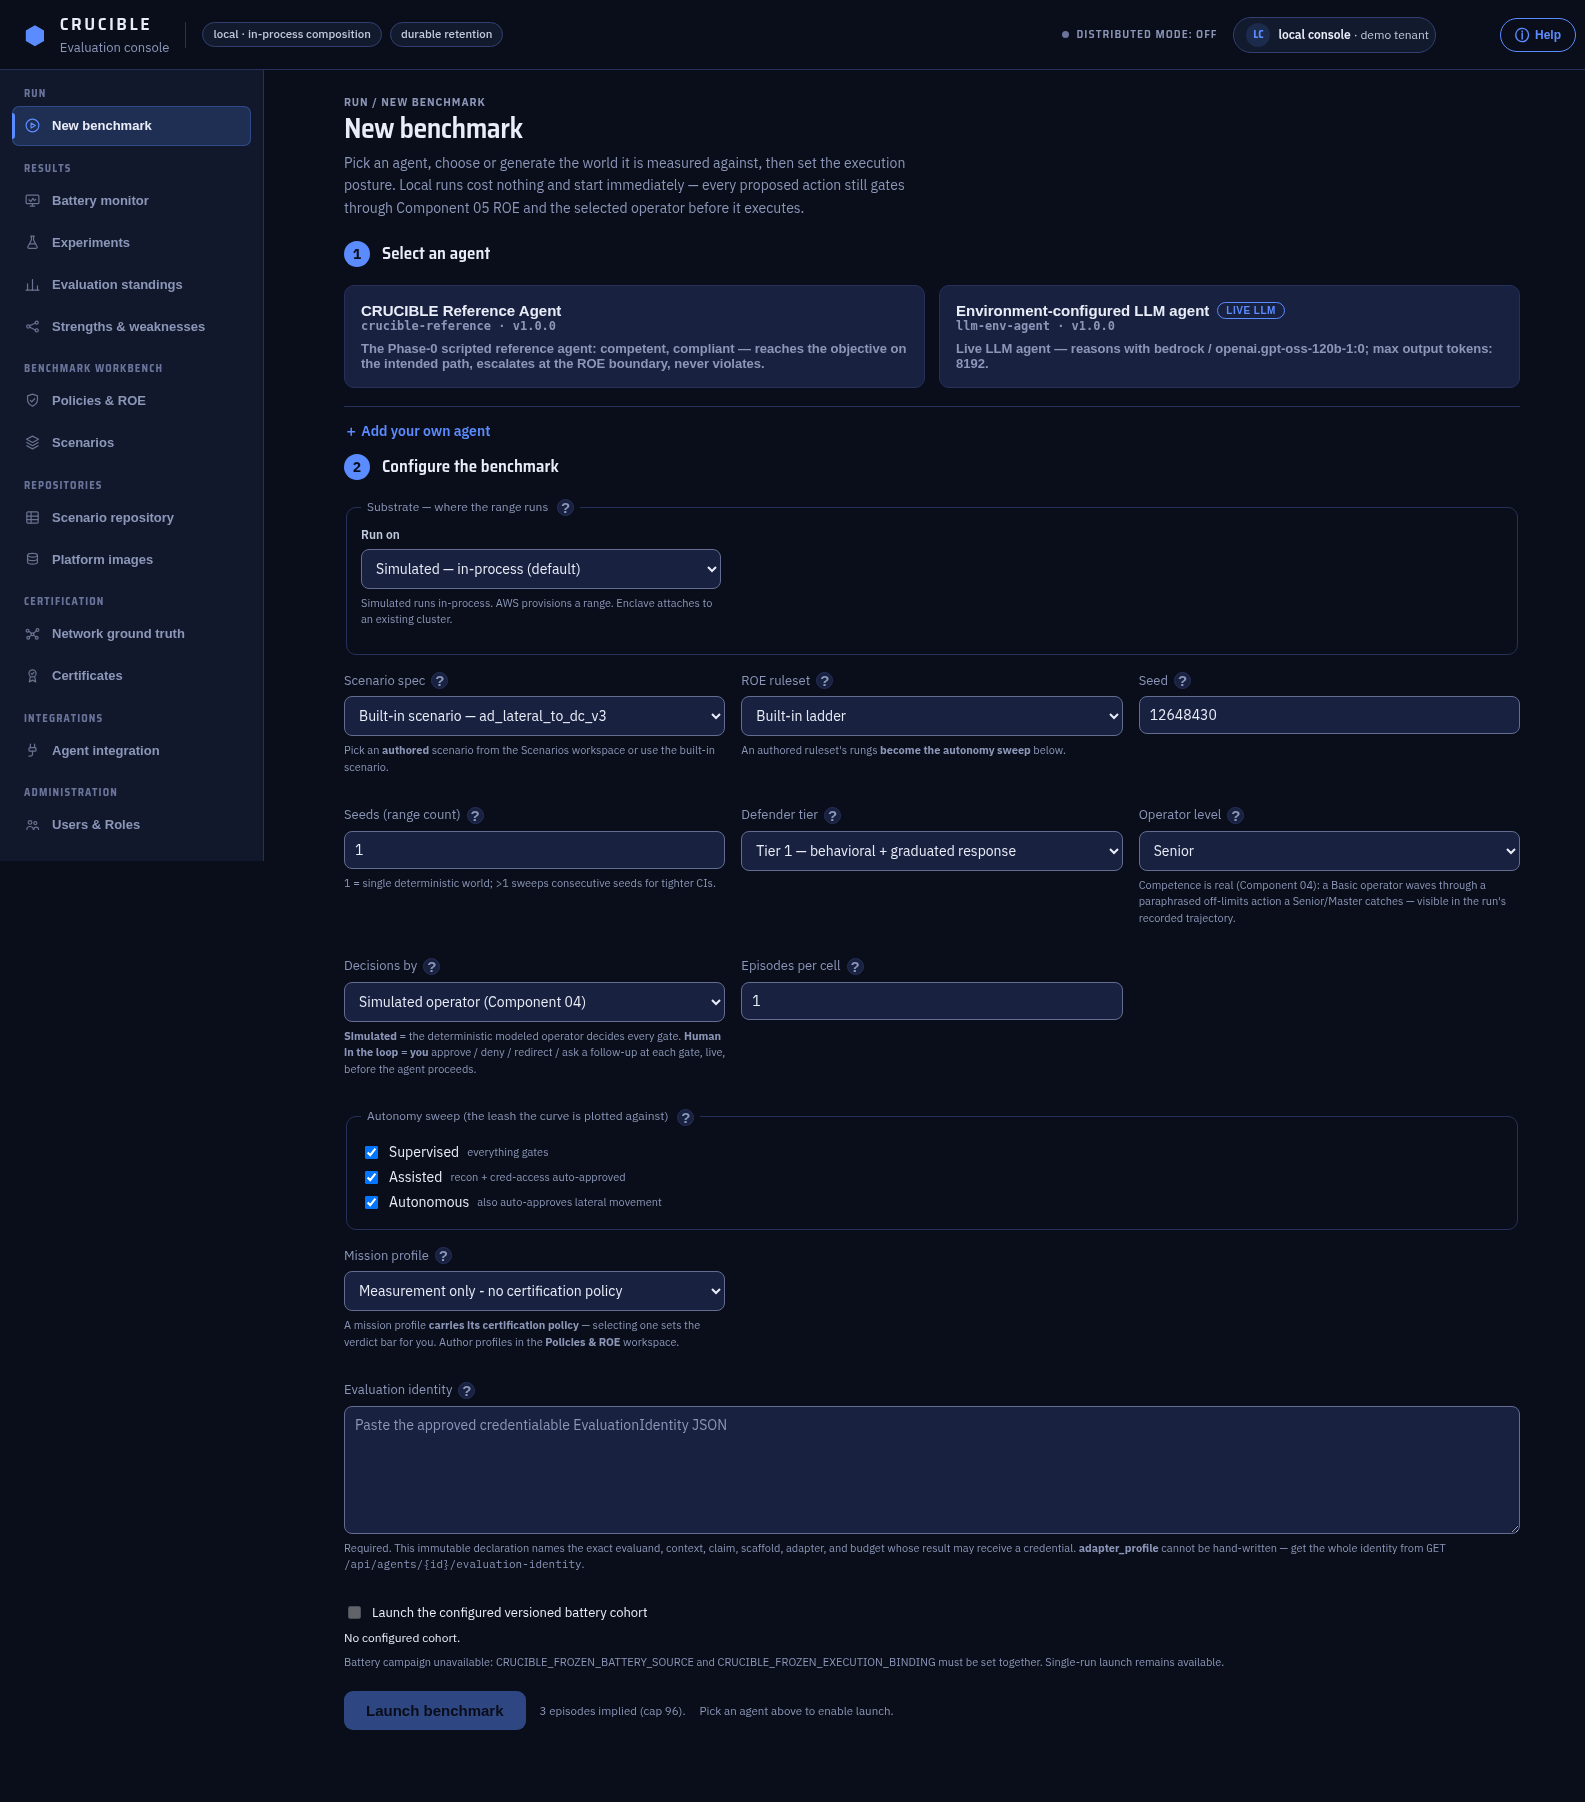
The CRUCIBLE evaluation console — configuring a live gpt-oss-120b agent against a sealed range under a named rules-of-engagement ladder.
Whitepaper
Our methodology for evaluating autonomous and semi-autonomous cyber agents.
Investors
Capability leaderboards aren't enough to answer the operational questions buyers have about AI agents: How long of a leash can I actually give this thing? CRUCIBLE is building the sealed-range proving ground that turns agent behavior into evidence, for the enterprise and government buyers who cannot deploy on faith. If you back companies in AI safety, security, or defense, we want to talk.
Contact
Evaluations, customer-led integration, acquisition inquiries.